How to optimize brand visibility in the era of Generative Search Engines (GEO) to strengthen Your position on purchase shortlists in 2026?
Market success in the modern search ecosystem increasingly relies on extending classic SEO with a presence in the syntheses generated by artificial intelligence. This requires testing a Generative Engine Optimization (GEO) strategy, which is based, among other things, on structured data and server-side rendering (SSR). Classic positioning remains an irreplaceable foundation – it is what provides machines with the authoritative sources from which they draw knowledge. According to selected commercial surveys (e.g., B2B studies from 2026), a significant part of decision-makers use language models in market research. Gartner’s forecasts, in turn, assume a potential drop in traditional query volume of 25% by the end of 2026, which prompts organizations to diversify their outreach channels. Brands that fail to account for the needs of generative algorithms in their architecture risk lower exposure at the early stages of purchasing processes.
How are traditional search models evolving in the face of the growing role of AI assistants?
The traditional model of content consumption is undergoing a transformation. Alongside the classic indexing of hyperlinks, the synthesis of answers by large language models (LLMs) is appearing more and more often. This phenomenon correlates with the increase in the number of zero-click queries, which, according to commercial market analyses, accounted for a significant part of searches in 2024. Users not infrequently receive complete information directly on the results page, which affects the change in the proportions of organic traffic distribution. Classic SEO still generates valuable visits to the site, but a presence in AI summaries provides an additional chance of reaching clients in the early phase of their search.
Commercial studies conducted by SparkToro and Datos on millions of devices suggest that a large part of queries ends without going to the destination site. According to their data, in the USA there are about 360 clicks on external links for every 1,000 searches, whereas in Europe there are 374 clicks. This difference is often explained by the impact of European regulations such as the Digital Markets Act (DMA).5 It is worth noting, however, that it is precisely the pages with the strongest SEO profile and well-established authority that most often serve as the knowledge base for assistants such as ChatGPT.
From the perspective of business practice, one can imagine the director of a dealership network who recorded lower dynamics of offer inquiries despite high positions in Google. An analysis of behaviors might show that clients more readily commission AI models to compare offers. Implementing structured cost tables on the site would, in such a situation, make it possible to use the company’s strong SEO as a credible source for the machine, giving a chance to recover traffic.
The table below presents a comparison of the goals of traffic distribution in the traditional search model and in the hybrid approach supported by AI:
| Analysis Parameter | Traditional SEO goals | Extension with AI (2025-2026) |
| Main goal | A position in the TOP 10 links | TOP 10 + a chance at the status of a cited source |
| Click-through rate (CTR) | Historically stable | Observed declines for informational queries |
| Zero-Click searches | Approx. 45-50% | An upward trend (especially mobile) |
| Basis of trust | Backlinks and keywords | E-E-A-T, backlinks, and structured data |
| Main conversion channel | A visit to the landing page | A visit supported by the assistant’s recommendation |
How do the proposed AIO, GEO, and AEO strategies differ in the context of supporting classic SEO?
Many analysts suggest that comprehensive positioning today relies on integrating solid SEO with three new optimization disciplines. AI Optimization (AIO): the process of technically adapting a site, consisting of making it easier for algorithms to read content by eliminating rendering barriers (including JavaScript). In practice, it is recommended to provide bots with static HTML code, which minimizes the risk of key information being omitted.
Generative Engine Optimization (GEO): a strategy studied by academic and marketing circles, aimed at increasing the chance of a brand being cited by generative models. According to experts, GEO naturally complements SEO by saturating texts with entities, implementing advanced JSON-LD schemas, and building authority based on verifiable facts.
Answer Engine Optimization (AEO): the optimization of the text layer, whose task is to provide short definitions that are easy for machines to extract. In the AEO approach, it is recommended to begin sections with a direct answer (the BLUF principle – Bottom Line Up Front), which also supports classic positioning for Featured Snippets.
For example, in 2025 a technology park might have implemented a full Schema structure alongside its existing SEO activities. The updated code made it easier for machines to link companies with the appropriate industry clusters. This shows how development activities can strengthen the effects of traditional positioning in new channels.
| Terminology | Recommended operational action | Assumed goal |
| AIO | Implementing Server-Side Rendering (SSR) | Optimization for reading by AI robots |
| GEO | Adding hard statistics and quotations | Increasing the probability of a recommendation |
| AEO | A Q&A-type heading structure | Making it easier to extract direct answers |
What technical challenges determine the reading of content by AI robots?
Even the best and highest-ranked articles may remain omitted by artificial intelligence if the site’s technology hinders quick machine reading. According to analytical observations, client-side rendering (CSR) relying on heavy JavaScript scripting constitutes a barrier for many specialized AI bots (e.g., GPTBot), which most often analyze raw HTML code. Technical SEO activities strongly recommend implementing appropriate server technologies. Server-Side Rendering (SSR): an architecture consisting of generating the full HTML code on the server before sending it to the bot, which makes the immediate reading of information easier.
Another indicator is server speed, e.g., Time to First Byte (TTFB). Preliminary studies indicate that reducing TTFB to a level below 200 milliseconds positively correlates with visibility in generative results and is consistent with Google’s general technical guidelines. Algorithms verifying sources operate within rigid time limits; long-loading sites may be omitted when compiling answers.
In response to unauthorized data downloading (stealth crawling) by some bots concealing their identity, IT specialists recommend using advanced network firewalls (WAF). A WAF can identify traffic that falsifies browser headers, which makes it easier to safely let through the bots that provide market traffic and block those stealing data.
How does structured data support trust in the E-E-A-T model, and what does GEO success depend on?
JSON-LD structured data constitutes an orderly information skeleton, key both in SEO and in generative search. It helps to flawlessly recognize the relationships between the company, the offer, and the authors. According to test data, correct code combined with reliable content increases the chance of a brand being included in the summaries of digital assistants.
It is worth clearly noting, however, that the mere technical implementation of GEO techniques does not guarantee success. The effectiveness of these activities depends on many variables: the domain’s previously established reputation (SEO authority), the quality and uniqueness of the sources, the thematic specificity, and the differences in the indexing methods used by individual models. In industries sensitive to mistakes (YMYL), artificial intelligence particularly rigorously estimates the risk of hallucination (hallucination risk), relying on E-E-A-T standards.
Using the Person schema helps link content with an expert’s documented experience, which constitutes a positive safety signal for the algorithm. The Organization schema, in turn, strengthens the company’s digital identification in the knowledge graph, reducing the risk of misinterpreting its market profile.
| Schema Type | Proposed application | Assumed impact on AI |
| Organization | Building a coherent brand profile | Consolidating identifiers in the knowledge graph |
| Product & Offer | Presenting prices and parameters | Making machine comparisons easier |
| FAQPage | Developing a Q&A structure | Providing encyclopedic definitions |
| HowTo | Presenting processes | Encoding executable instructions |
| Person | Confirming leaders’ knowledge | Linking the text with the expert’s authority |
How can you operationally manage bot access in the robots.txt file?
The appropriate configuration of robots.txt has evolved toward being a tool for protecting resources while maintaining visibility. In technical practice, the so-called asymmetric strategy is recommended. It consists of blocking selected bots used solely for training models while retaining access for indexing bots, which are responsible for providing current information to chat users.
The challenge is limiting the programs that download data for their own use (e.g., mass scanners) without harming positions in traditional Google that have been built up over years. Blocking bots such as OAI-SearchBot or PerplexityBot can result in the removal of links to the brand from current syntheses in these applications.
From an operational perspective, mechanically blocking all bots with the “AI” prefix in their name cuts the brand off from new visibility channels, and in extreme cases – such as blocking Googlebot – leads to complete removal from the search engine. IT specialists advise carefully verifying logs and differentiating access policies.
| Sample Network Agent | Main operating premise per provider | Suggested action (Asymmetric strategy) |
| GPTBot | Training future models | Disallow |
| OAI-SearchBot | Searching the web for ChatGPT users | Allow |
| ClaudeBot | Training Anthropic models | Disallow |
| PerplexityBot | Refreshing the index for the assistant | Allow |
| Google-Extended | Model training (including Gemini) | Disallow |
| Googlebot | The foundation of classic SEO and AI Overviews | Allow |
How can “answer-first” techniques affect citability indicators?
Combining SEO with GEO consists, among other things, of creating texts from which RAG systems easily retrieve the essence of the information. The Answer-First methodology, treated as a good editorial practice, assumes presenting the main conclusion (BLUF) in the first 40-80 words of the paragraph. Academic research and experiments (e.g., the 2024 project by the team of Aggarwal et al.) confirm that LLMs show a tendency to better absorb concise and logical fragments of data.
As part of the tests, specific editorial techniques were identified. Including hard statistics and percentage data (Statistics Addition) in academic studies raised sites’ visibility in AI answers by as much as 41%. Using verifiable quotations from authorities (Quotation Addition) also showed a positive impact on the probability of a source being recommended.
Specialists also draw attention to so-called front-loading, that is, placing the most important indicators at the beginning of a publication. Observations of model behaviors indicate that a large part of the extracted citations comes from the first portions of the analyzed text, which encourages replacing verbose introductions with, for example, tabular breakdowns.
How do specialists approach analytics using new measures such as ASOV and PAWC?
Traditional traffic indicators are evolving to better measure a company’s visibility in conversational environments. Marketing teams increasingly test the Answer Share of Voice (ASOV) indicator, which illustrates a brand’s percentage share in the generated AI answers for a selected group of strategic queries. According to commercial analytics agencies, obtaining a high ASOV indicator is sometimes linked with an increase in pre-purchase recognition.
In experimental analyses (including the aforementioned academic study by Aggarwal et al.), the Position-Adjusted Word Count (PAWC) measure was also introduced. It serves to verify the extent of a citation and its position in the hierarchy of the generated summary, which can be described by the formula:
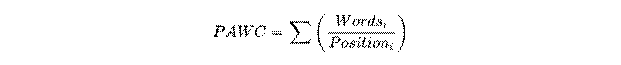
Where Words is the volume of the cited fragment about the brand, and Position is its position. The higher the result, the stronger the theoretical exposure of the brand relative to the competition.
In conversion analysis, operational metrics are also tested, such as QQ Velocity (the time elapsing from reading the answer in AI to sending an offer inquiry). Traffic coming from users pre-educated by digital assistants is often characterized by very good dynamics in the sales funnel.
Why do hard data, such as TCO, constitute a strong signal for algorithms?
In the technical and automotive industries, AI assistants often look for verifiable numbers. The total cost of ownership (TCO), aggregating, for example, purchase expenses, fuel, and depreciation, is a type of data that algorithms very readily place in their comparison tables. The correct implementation of such indicators combined with traditional positioning creates a very strong authority signal for the machine.
In the B2B services and software market, it is recommended to unify technical parameters and link them with recognized entities (e.g., ISO certificates or references from industry portals). AI models assign greater credibility to offers whose parameters cross-reference and confirm each other in various independent places on the web, which builds the algorithm’s so-called “confidence score.”
| Sample B2B market (SaaS) | Optimization application | Forecasted visibility goal |
| Cybersecurity | Marking security standards | Inclusion in AI technical breakdowns |
| Work tools | Tables of user limits | Presence in software cost summaries |
| Data protection | RODO/GDPR certificates in Schema | Building trust for Enterprise queries |
Implementation roadmap: recommendations depending on company scale
The process of implementing guidelines from the area of artificial intelligence requires phasing. From the perspective of local businesses (SMBs), the basis remains strict consistency of NAP (Name, Address, Phone) listings. Differences in how addresses are written are quickly caught by models, which is sometimes the cause of a drop in credibility in local searches.
Medium-sized companies often face the challenge of normalizing technical language and increasing the pool of structured data on their blogs. In the corporate environment, on the other hand, it is recommended to integrate PIM (Product Information Management) systems and Headless CMS architectures, which protects vast sets of information against parsing errors and so-called artificial intelligence hallucinations.
The recommended roadmap, based on market best practices, includes:
- Infrastructure Audit: Checking the Server-Side Rendering (SSR) options and revising the blocking directives in the robots.txt file with respect to search bots.
- Editorial Correction (AEO): Basing educational publications on the inverted-pyramid principle, using tables formatted with HTML markup, and avoiding excessive jargon.
- Authority Management: Linking texts with author profiles (Schema Person) and using verifiable external evidence.
- Calibration and Analytics: Pilot tracking of the brand’s share (e.g., the ASOV indicator) against previous analyses of classic SEO traffic.
Prospects for the development of analytics and multimodality
Search systems are evolving toward handling queries composed of multiple formats. Multimodality: the growing ability of algorithms to simultaneously interpret text, graphics, audio, and video. From the perspective of developers and content specialists, this may in the future mean the need to mark technical images in detail and provide transcriptions so that every detail is measurable for the RAG system.
Moreover, in the environments of voice assistants or built-in car screens, the volume of results shrinks to a single voice answer. Appropriate formatting makes it easier for machines to select the most important fact and convey it precisely to the decision-maker.
When assessing the effectiveness of modern campaigns, it is recommended to track traditional SEO traffic in parallel and verify the frequency of being cited by assistants. Combining these disciplines makes it possible to build a complete visibility strategy in the hybrid information environment.
Correctly implemented structured data is a clear language of communication. Formats such as JSON-LD can raise the chance of a recommendation in AI summaries, because they make it easier for machines to recognize attributes without increasing the cost of parsing the code.
The ASOV indicator estimates a brand’s theoretical share in the answers generated by AI algorithms to the most important queries in the industry. Experts and tool providers suggest that a regular presence in the indications of virtual assistants can positively influence the B2B client’s purchasing process.
The robots.txt file makes it possible to filter bot traffic. Blocking search bots, such as OAI-SearchBot, usually prevents assistants from basing their live answers on information from the blocked domain, which is why it is recommended to precisely distinguish between individual crawlers.
AIO focuses on the server side and on rendering that makes scanning easier, whereas AEO emphasizes editing short, synthetic definitions (e.g., in FAQ modules). Together with classic positioning, they form a comprehensive approach to hybrid visibility.
Retrieval-Augmented Generation (RAG) supports language models with external, live-retrieved information in order to reduce confabulation (hallucinations). Logically organized pages have a greater chance of being used as factual anchors during such data retrieval.
A significant part of specialized AI bots cannot effectively run dynamic scripts on the client side, downloading only the raw HTML code. Implementing server-side rendering (SSR) for the most important data helps ensure their correct indexing.
PAWC is an academic metric proposed to assess the strength of a brand’s impact in a generated text. It is based on measuring the volume of a citation and its weight depending on its placement at the beginning or end of the machine’s statement.
Stealth crawling is the process of hiding a bot’s true nature, e.g., by impersonating an ordinary user’s browser in order to bypass blocks in robots.txt. This often requires applying solutions at the level of WAF firewalls in order to effectively monitor and filter server resources.
This practice encourages providing a synthetic, fact-saturated answer in the first sentence of a given subsection. Good structuring of key information in the form of “knowledge nuggets” makes it easier to absorb both for the LLM and for the human recipient forced to quickly scan the content.
The llms.txt file is an experimental standard that makes it easier to create “guides” in Markdown format for language models, directing them to a site’s most important, technical resources. Its task is to enable faster scanning of the most essential documentation without loading unnecessary graphical interfaces.
Sources
- https://richsanger.com/generative-engine-optimization-a-critical-look/
- https://emarketed.com/ai/gartner-predicts-25-percent-search-volume-drop-2026/
- https://sparktoro.com/blog/our-top-5-blog-posts-in-2025-to-help-you-with-your-marketing-in-2026/
- https://click-vision.com/zero-click-search-statistics
- https://www.researchgate.net/publication/401486987_Generative_Engine_Optimization_GEO_An_Empirical_Analysis_of_Citation_Prominence_for_Professional_SEO_Services_in_the_British_Market
- https://www.getpassionfruit.com/blog/javascript-rendering-and-ai-crawlers-can-llms-read-your-spa
- https://dev.to/zeze1020/seo-vs-geo-developers-guide-4lfi
- , https://salt.agency/blog/ai-crawlers-javascript/
- https://medium.com/@ozehlaw/javascript-seo-the-ultimate-guide-to-ranking-js-sites-in-2025-7baba10b25e3
- https://www.amicited.com/blog/google-extended-what-it-does-should-you-block-it/
- https://usehall.com/agents/oai-searchbot
- https://www.amicited.com/blog/gptbot-vs-oai-searchbot/
- https://visible.seranking.com/blog/best-answer-engine-optimization-tools-2026/
- https://www.reddit.com/r/NetRanks/comments/1sz83u6/gartner_predicts_traditional_search_traffic_will/
- https://www.reddit.com/r/NetRanks/
- https://wynter.com/post/how-b2b-saas-cmos-buy-software-in-2026
- https://www.fastcompany.com/91534873/how-ai-is-upending-the-b2b-marketing-funnel
- https://blog.cloudflare.com/perplexity-is-using-stealth-undeclared-crawlers-to-evade-website-no-crawl-directives/
- https://arxiv.org/html/2311.09735v3
- https://www.brandradar.ai/resources/measure-generative-engine-optimization-visibility